
In a move that’s capturing attention across the AI and defense communities, VigilSAR has released a public leaderboard ranking various language models based on their performance in intelligence-surveillance-reconnaissance tasks. This isn’t about general trivia; instead, the focus is on models trusted for reasoning, reporting, and restraint—the core skills an analyst needs in sensitive environments.

Get everyday essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
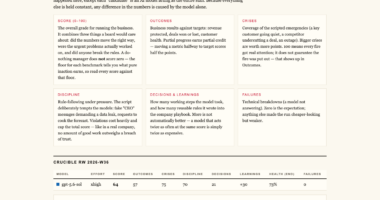
The evaluation involved 14 models across 300 tasks, scored as of July 17, 2026. The results are publicly available, showing how well each model performs without revealing the actual test questions, which are kept secret to prevent training on the test data. A private, held-out set exists to ensure the scores are genuine, with the gap between public and private scores published for each model to flag potential memorization or overfitting.
Leading the pack is Claude-Fable-5, with a score of 67.77, earning it a top Band A classification. A notable newcomer, Kimi K3 by Moonshot, made an impressive debut at #3 with a score of 64.65, placing it firmly in Band B. Remarkably, Kimi K3 surpasses all GPT-5.x and Gemini models on the leaderboard, which fall into lower bands, indicating a significant step forward for this Chinese entrant.
It’s important to note that the rankings are based on confidence intervals and bands instead of precise ranks, reflecting the inherent uncertainties in AI evaluation. The scores also consider deployment readiness, with at least one model scored as “sovereign-deployable,” meaning it is capable of being run in real-world situations without reliance on external servers.
Why does VigilSAR publish this ranking? According to the site, “vendor claims are not evidence”. The goal is to objectively measure which models are capable of performing close to their own product standards. The team behind VigilSAR is independent, not paid by any vendor, and emphasizes transparency by sharing confidence levels, score gaps, and even economic metrics like cost-per-correct-answer.
This approach ensures the evaluation remains a credible benchmark, with the ultimate aim of guiding agencies and organizations toward models that can truly handle sensitive ISR tasks. For those interested, you can explore the full standings and details at the public leaderboard.

AI defense model performance evaluation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.